nOps AI Optimization Recommendations: Closing the Gap From Insight to Verified Savings
As AI adoption scales across providers, foundation models, and engineering teams, managing AI infrastructure costs has quickly become a core operational challenge. But for most engineering and FinOps leaders, the bottleneck isn't knowing that costs are rising—it's taking safe, confident action to reduce them.
Today, we’re excited to launch nOps AI Recommendations: an end-to-end workflow built to bridge the gap between AI cost visibility and verified billing savings.
The Problem: Why AI Optimization Stalls Out
Traditional cost tools provide dashboards showing where AI spend goes. However, converting raw visibility into actual savings remains frustratingly high-friction for engineering teams:
- Low trust in black-box estimates: Generic recommendations rarely explain the underlying assumptions, leaving engineers skeptical about risk and quality impacts.
- High evaluation and execution effort: Translating a suggestion into code, prompts, or configuration changes requires manual context-gathering across billing and production systems.
- Unverified outcomes: Even when changes are deployed, teams lack automated feedback to confirm whether expected savings actually materialized on the monthly cloud bill without degrading performance.
The 4-Stage AI Optimization Workflow
Rather than adding another passive reporting surface, nOps AI Recommendations provides a continuous 4-stage workflow designed around how engineering and FinOps teams actually work together.
Stage 1: Overview & Rapid Evaluation
Instantly assess whether an opportunity is worth pursuing. At a glance, teams see estimated monthly savings, percentage cost reduction, required implementation effort, confidence level, change risk, and rollback options.
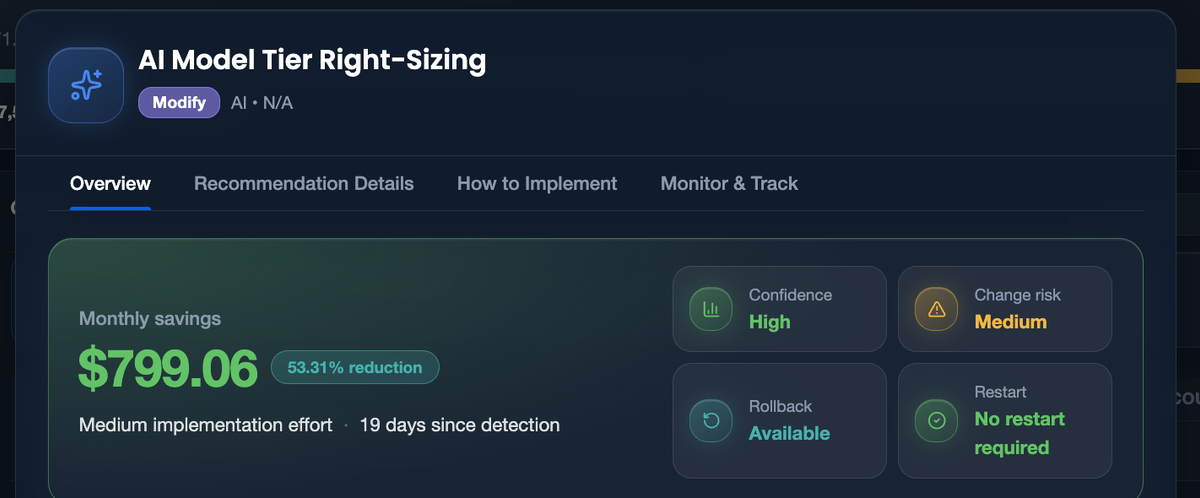
High-level optics provide immediate clarity on savings, effort, and change risk.
Stage 2: Transparent Evidence & Trust
Build engineering trust with complete explainability. nOps exposes exact current and suggested configurations, historical billing lookbacks, workload ownership, pricing models, and explicit capability trade-offs.
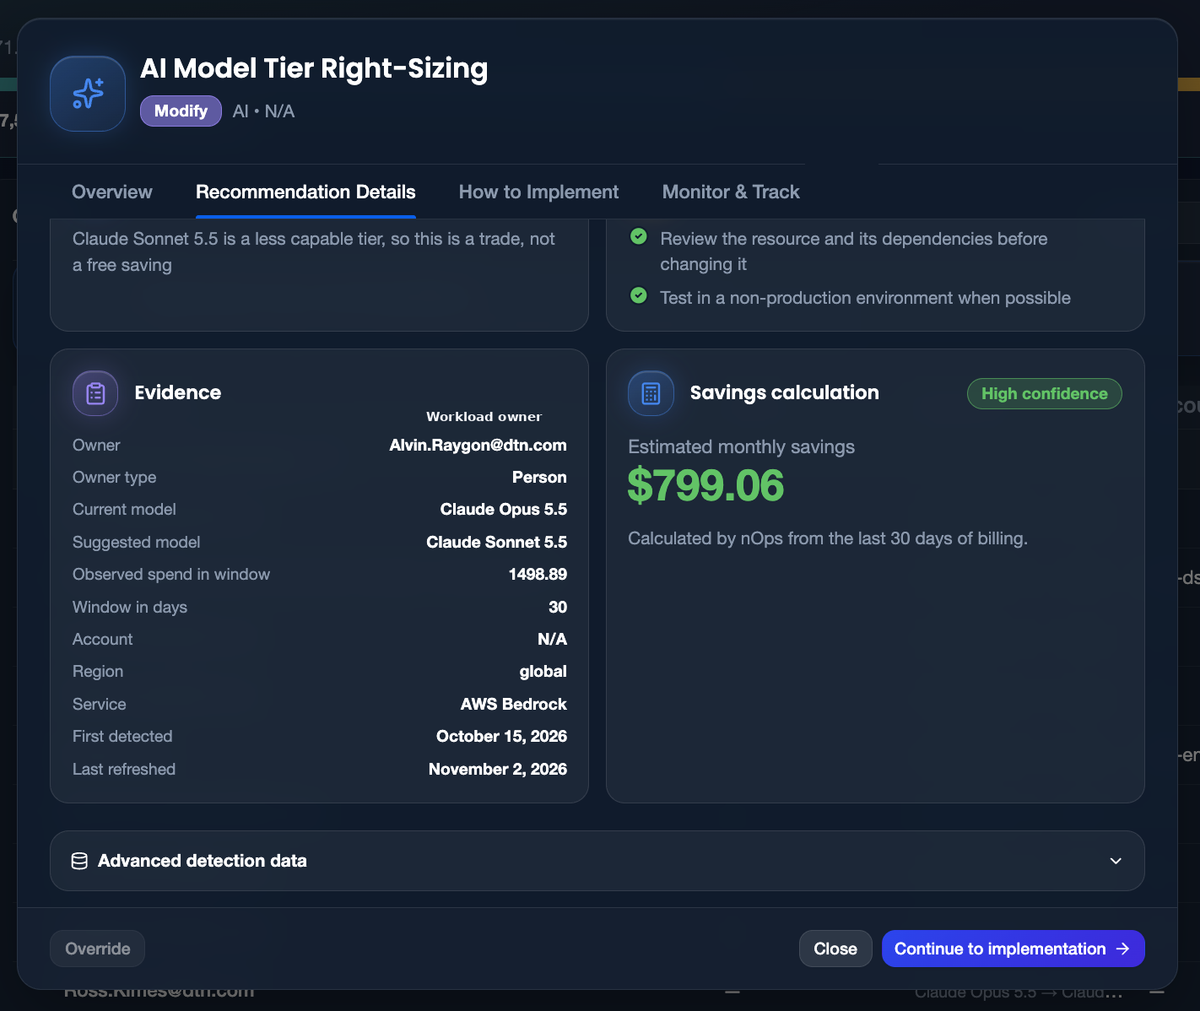
Transparent evidence and underlying math behind every recommendation.
Stage 3: Seamless Implementation & AI Handoff
Move directly from insight to action. Teams can follow step-by-step instructions, generate exact CLI commands/scripts, or hand off rich context packages directly to modern developer tools like Claude Code, Cursor, Codex, or Clara FinOps AI Agent.
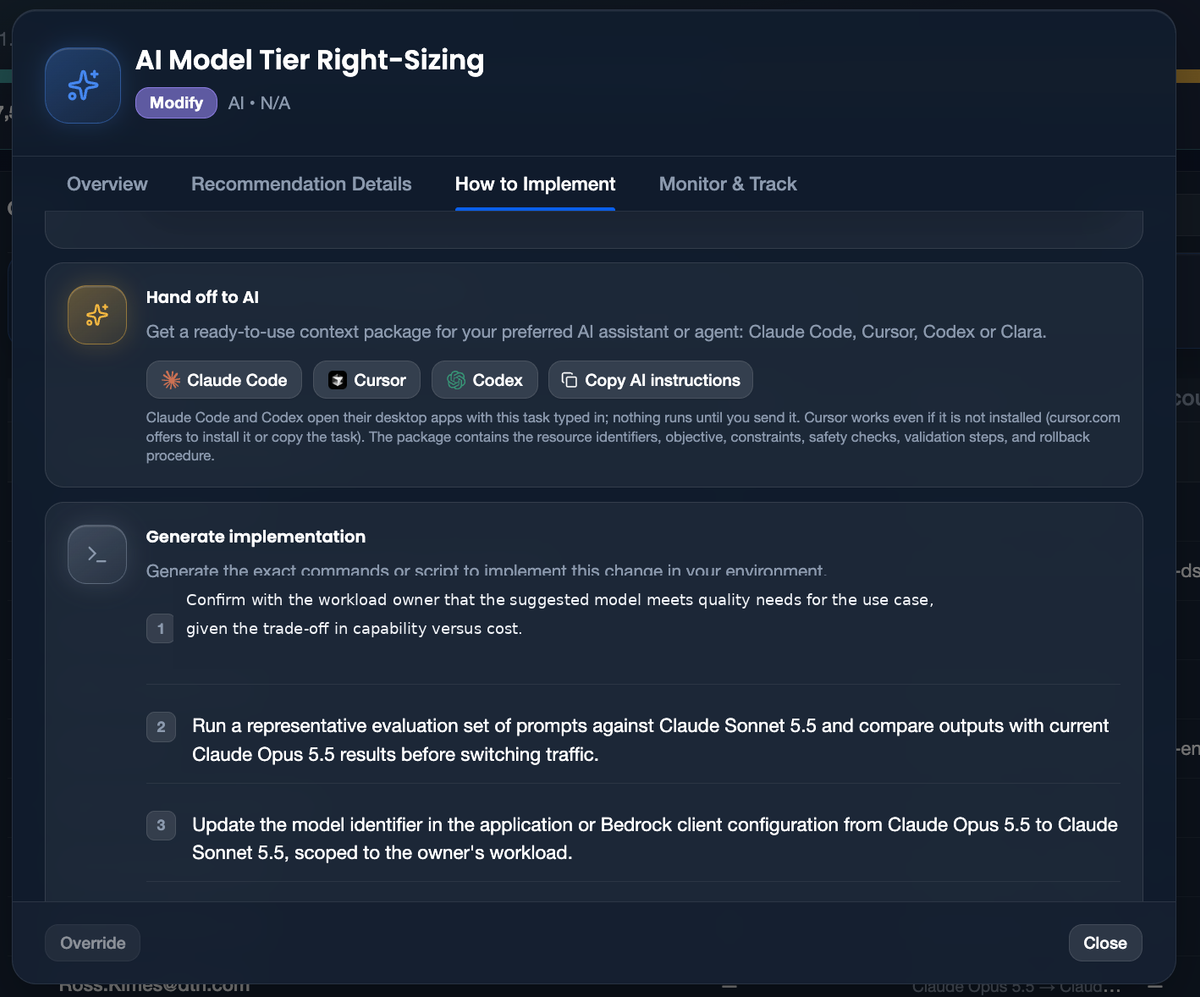
Implementation guidance with one-click handoffs to developer AI agents.
Stage 4: Automated Verification & Tracking
Optimization doesn't end at deployment. nOps continuously tracks post-change telemetry to verify workload health, monitor for error spikes, and confirm that projected savings reflect on actual cloud invoices.
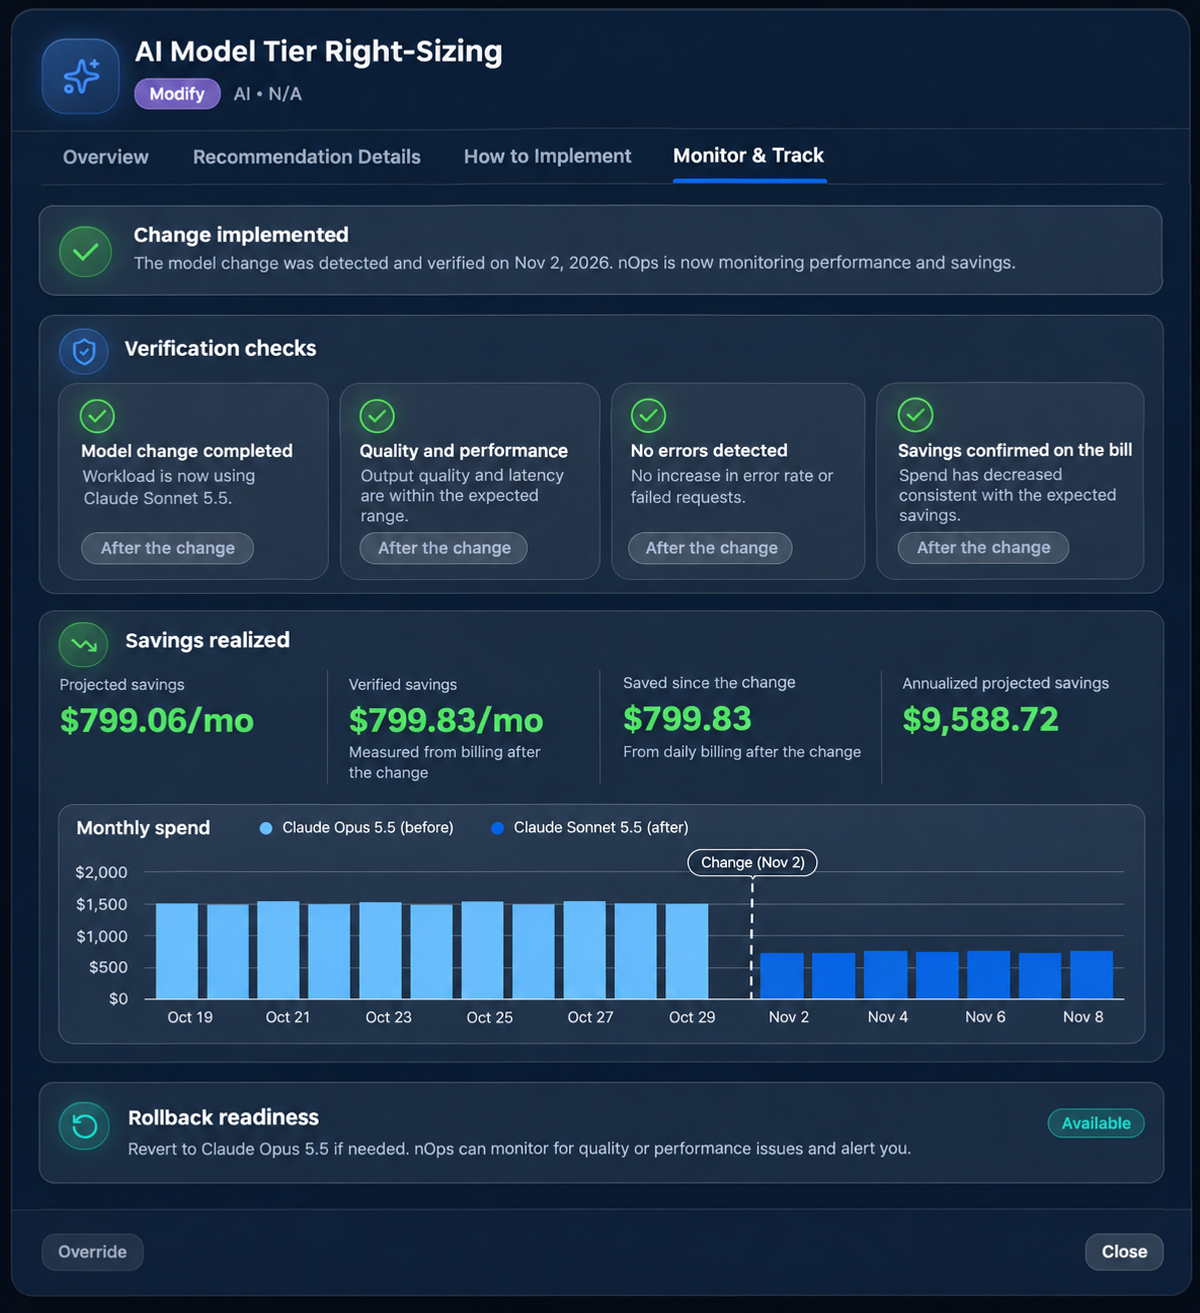
Closed-loop verification comparing projected vs. verified savings in real time.
Real-World Impact: ~$88K in Annual Savings from a Single Action
The power of this workflow is best demonstrated in production. One of our customers evaluated an AI Model Version Upgrade recommendation generated by nOps. By following the integrated implementation guide and verifying post-change telemetry, the team successfully upgraded their model baseline—placing them on track for ~$88,000 in annualized verified savings from a single intervention.
As shown in nOps Explorer below, the impact on daily AI spend was immediate and sustained:
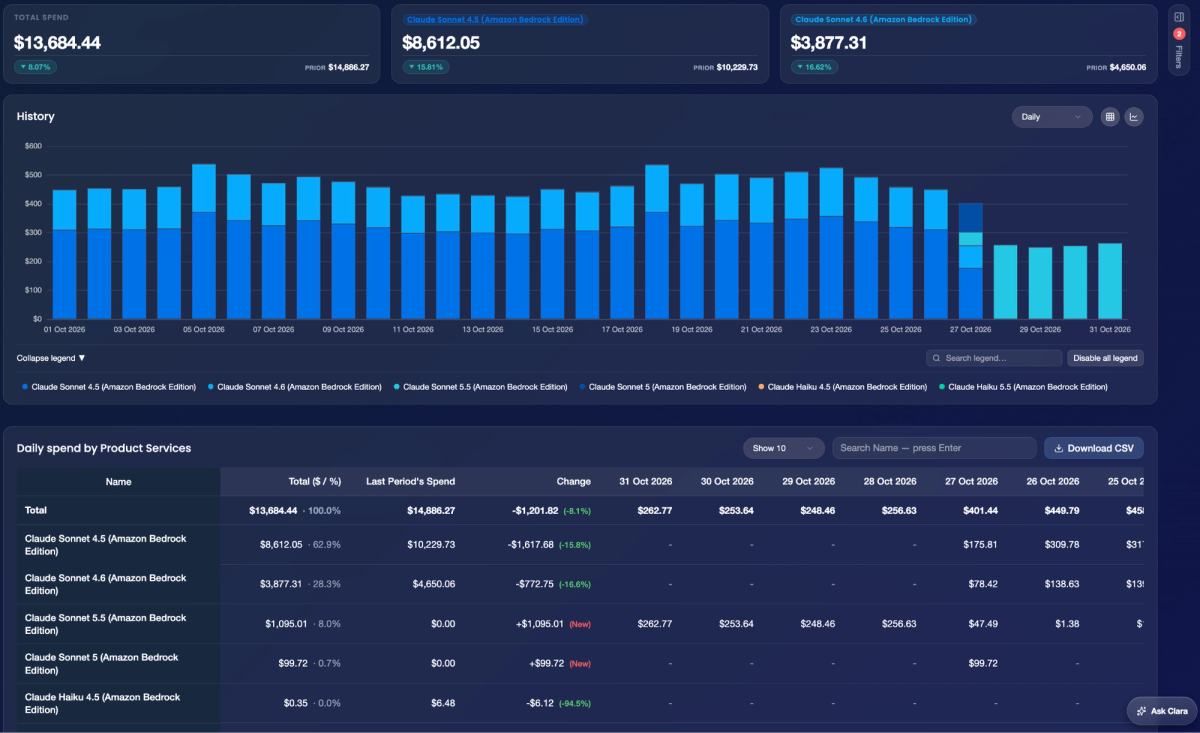
Actual customer result. Daily AI spend declined after implementation of one AI Model Version Upgrade recommendation, putting the customer on track to save approximately $88,000 annually. Customer-identifying details have been anonymized.
This is a simple example, but an important one: even one well-targeted model change can create meaningful financial impact when applied to production AI workloads. The value of the recommendation is not just finding the opportunity — it is making the change easy to evaluate, implement, and verify.
A Broad Spectrum of AI Optimization
Effective AI cost management goes beyond model selection. nOps continuously analyzes usage patterns across several key architectural vectors:
- Model Tier Right-Sizing: Match workload requirements with the most cost-effective model capability tier.
- Model Version Upgrades: Capitalize on price-performance improvements in newer model releases.
- Long-Context Optimization: Detect excessive prompt context that inflates per-request token consumption.
- Prompt Cache Optimization: Identify opportunities to increase cache hits and reduce redundant processing.
- Speed Tier Optimization: Align latency SLAs with service tier pricing to avoid paying premium rates for non-realtime tasks.
- Idle Infrastructure Elimination: Automatically flag unused resources like idle SageMaker instances.
- Batch Workload Execution: Shift non-urgent interactive calls into lower-cost batch processing queues.
Measuring Genuine Success
At nOps, we don't measure the success of AI Recommendations by the number of insights generated. True success is defined by engineering action and verified financial outcome:
- Action Rate: The percentage of recommendations reviewed and deployed by engineering teams.
- Speed to Implementation: Reducing the time required to evaluate, test, and execute changes.
- Verified Dollars Saved: Net cost reduction confirmed on billing invoices post-change.
Get Started Today
In nOps, go to Settings and connect all of your AI integrations, so recommendations cover your full AI spend. Your recommendations then appear under Inform → Recommendations, each with its estimated savings and the evidence behind it, ready to hand off to Claude Code, Cursor, or Codex.
If you’re already using nOps…
Have questions about AI Recommendations or connecting your AI integrations? Reach out to your Customer Success Manager or visit our Help Center. If you’re not sure who your CSM is, send our Support Team a message.
If you’re new to nOps…
nOps was recently ranked #1 with five stars in G2’s Cloud Cost Management category, and we optimize $5+ billion in AI and cloud spend for our customers.
Join our customers using nOps to understand and control your AI and cloud costs by booking a free savings analysis with one of our experts.